RQ1Paired smoke test
Language as action
Does an expert demonstration improve closed-loop robot control?
With expert demonstration vs. without expert demonstration
Overall success rate
With demonstrationWithout demonstration
Results by task
Success rate · successful / completed| Task | Model | With demo | Without demo | Difference |
|---|
Task examples
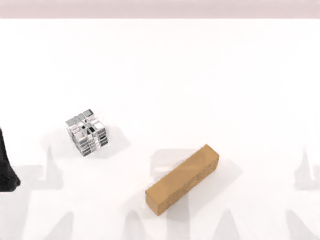
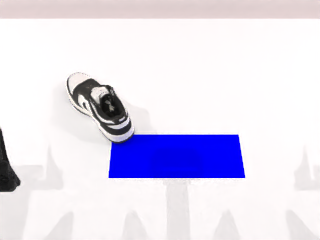
Experimental protocol
- Paired cases
- Five fixed, expert-validated initial states per task, shared across models and conditions. Each condition starts from the same scene state; later observations depend on the model's actions. Task 34 contains three left-placement and two right-placement cases; its shared demonstration is a left-placement episode.
- Model input
- Head, left-wrist and right-wrist RGB images; joint states, end-effector poses, fixed robot geometry and the last four actions. No test-object coordinates or scripted task actions are supplied.
- Demonstration
- One shared successful expert episode from a separate seed, replay-verified through the same action interface. The full sequence of observations, robot states and joint actions is included on every decision: 31 actions for Task 34, 32 for Task 35 and 64 for Task 36. The entire demonstration prefix is removed in the no-demo condition; current-step input construction is otherwise identical.
- Action and budget
- One JSON action containing 14 absolute joint/gripper targets per decision. Up to 96 decisions, stopping immediately on success. All three models use medium reasoning and the same output schema, via Sub2API.
- Scoring
- Original RoboTwin task-success checks. Completed invalid-action and exhausted-budget episodes count as failures; infrastructure-blocked episodes do not. Overall success is the equal-weight mean of the three task rates, available only when all paired cases are complete.
- Prompt alignment
- In both Task 35 conditions, the final sentence referring to the reference demonstration is removed; the explicit mat, sole, toe-direction and gripper requirements remain unchanged.
This is an in-context demonstration comparison, not fine-tuning. Five cases per task provide a preliminary signal, not a statistically established effect. Luna was stopped and is excluded. Exact runtime inputs and raw outputs are retained separately from these public aggregates.
Paired case outcomes
| Task / case | Model | With demo | Without demo |
|---|
Expert demonstration count
Follow-up study · 24 Sep 2026 snapshot0, 1, 3 or 12 demonstrations · 10 test cases per condition · 96-step execution budget
| Task | Model | 0 demos | 1 demo | 3 demos | 12 demos |
|---|---|---|---|---|---|
| Task 35 Place Shoe | GPT-6 Astra | 1/10 | 5/10 | 7/10 | 10/10 |
| Task 35 Place Shoe | GPT-5.6 Sol | 0/10 | 1/10 | 2/10 | 2/10 |
| Task 36 Place Object Basket | GPT-6 Astra | 1/10 | 4/10 | 7/10 | 9/10 |
| Task 36 Place Object Basket | GPT-5.6 Sol | 0/10* | 1/10 | 2/10 | 2/10 |
Results could not be loaded.